Crawl and indexability
Review important URL groups, internal discovery, canonical signals and the differences between what should be indexed and what is currently accessible.
Turn crawl, indexing and architecture findings into a prioritised implementation backlog.
Review important URL groups, internal discovery, canonical signals and the differences between what should be indexed and what is currently accessible.
Assess how service, category and supporting pages relate. Identify changes that make important journeys easier for people and crawlers to follow.
Plan URL mapping, redirects and pre-launch checks around the release. Agree who implements, approves and monitors each change.
Each priority includes affected examples, the reason it matters, an owner and a verification method. Close the loop after implementation.
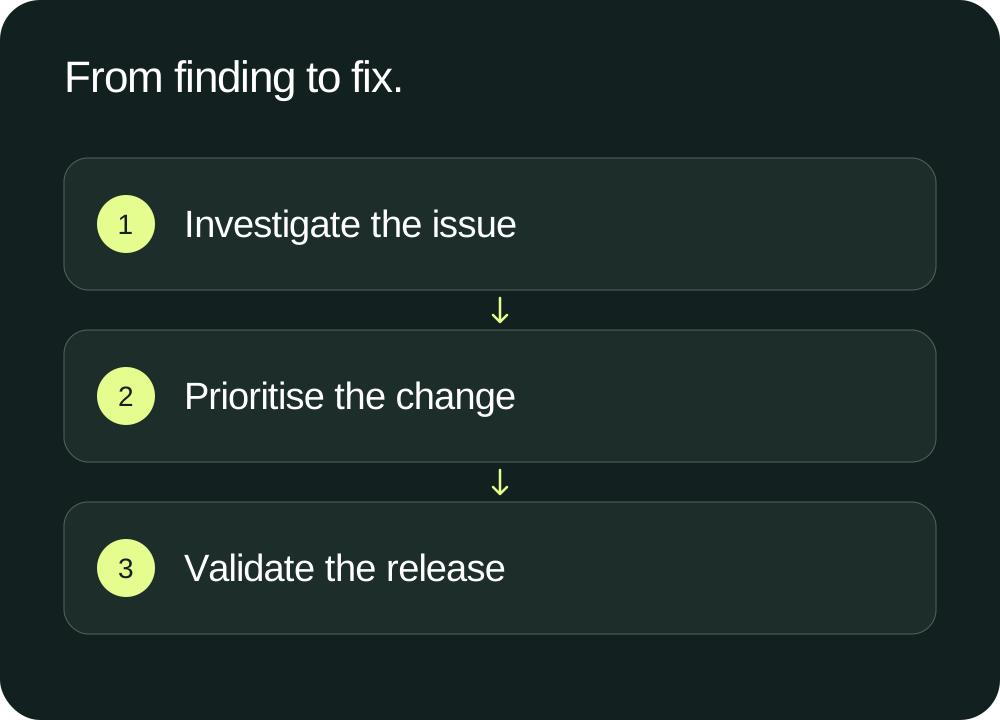
An issue is only useful when someone can act on it. We connect the affected pages with the recommended change, an implementation owner and a way to check the result.
Useful outputs: Affected URLs, a prioritised implementation brief and validation criteria.
Useful for redesigns, platform moves, complex catalogues or important pages that are not being discovered. We agree the templates, markets and environments in scope before crawling.
A prioritised issue register, URL examples and developer-ready recommendations. Dependencies and acceptance checks make the backlog actionable.
Your development team owns its release process unless implementation is separately agreed. We explain the search requirement, review changes and validate the agreed checks.
Tell us where technical uncertainty is slowing your team down. We’ll help you explore the priorities, dependencies and implementation support your site needs.